One Bad PDF Shouldn't Fail the Batch. One Bad API Key Should.
FDAgent's nightly job turns FDA inspection PDFs into searchable observations. In July every failure in it got a kind: one document's problem, or the whole run's. A retry limit only works if an outage can't quietly use it up.
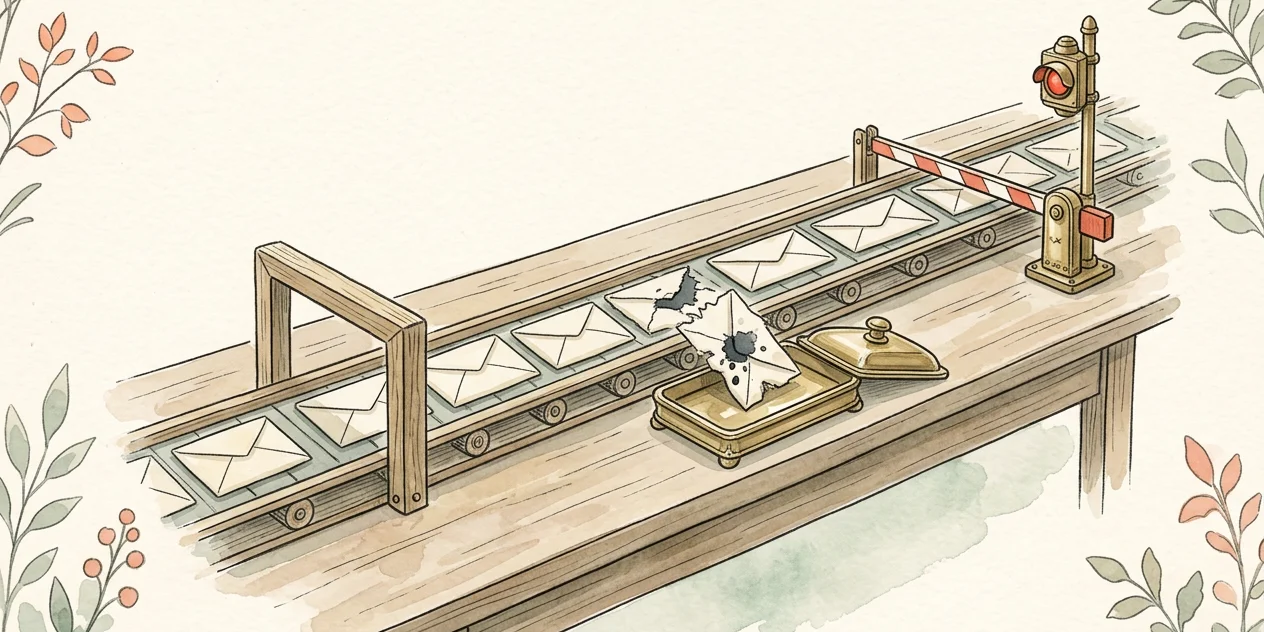
A batch job that treats every failure the same way gets one of two things wrong. Either one bad document stops the run for everyone, or an outage gets blamed on every healthy document in the batch.
FDAgent runs a nightly job over Form 483s, the observations FDA investigators leave after an inspection. It works through FDA's reading-room backlog 100 PDFs a night, runs OCR on the scanned PDFs, has a model parse each document into structured observations, and syncs those rows into a vector index so they can be searched.
Getting it to run at all
For 12 days in July that job failed in about ten seconds every night. The workflow never told its package-manager setup which version to install, so it stopped before doing anything.
Fixing that on July 25 exposed two more problems. The first real run enriched 92 PDFs, then got through 121 of 150 parse candidates before GitHub cancelled it at its two-hour timeout. And the step that syncs observations to the vector index exited immediately, because the workflow never passed it the credentials it needed. Two small fixes later, the run passed end to end.
A run that works once says nothing about the night a provider is down.
Two ways to get failure wrong
A nightly batch over hundreds of documents fails in two very different ways.
Some failures belong to one document. The PDF is gone from FDA's site. The OCR text is corrupt. The model won't parse one document, or it's too long for the model's context. Some of those are worth one more try. Most aren't, and retrying them every night forever wastes every run.
Other failures belong to the whole run. FDA's server is rate-limiting or down. The model provider rejects the key, or the configured model doesn't exist. A database write fails. Every document in the batch will fail the same way, and none of them is at fault.
Treat a run failure as a document failure, and an outage charges every healthy document a retry. With a retry limit, a few bad nights quarantine documents that were never broken. Treat a document failure as a run failure, and one bad PDF stops the batch for everyone.
Three kinds of failure
The change merged on July 26 makes every failure declare which kind it is.
- A terminal failure is the document's problem, and it won't change: a PDF that returns 404 or 410 or is over the size limit, OCR text too poor or too corrupt to use, or a document the model refuses to parse. It's quarantined on the first attempt.
- A transient failure is the document's problem, but it might not recur. It retries once a day, 20 hours apart, and is quarantined after three attempts.
- A systemic failure is the run's problem. FDA returning 403, 408, 429 or a 5xx, a model provider returning an authentication, rate-limit or server error, or a database write failing all abort the batch, and no document is charged an attempt.
The rule for HTTP 400 is the most specific. Some 400s really are about the document: the context length was exceeded, or a content filter fired. Only those named codes count against the document's retry budget. Any other 400 aborts the batch, because, as the comment in the classifier puts it, "an unknown 400 usually means the configured request/model is invalid." Anything else the classifier can't place is charged to the document, and three strikes quarantine it.
One exception is deliberate. A fetch that gets no HTTP response at all, such as a DNS or socket error, is charged to the document, because it may be one dead link. If FDA disappears entirely, each document is still charged an attempt, but the run fails loudly: a run that had candidates and enriched none exits with an error.
Quarantine isn't permanent. A document's retry state clears automatically when new OCR text or a successful parse is written for it, and a flag retries the quarantined set on purpose. The backlog report now splits documents waiting to be parsed into active, deferred and quarantined, so a growing quarantine shows up.
The same change split the job into three isolated jobs: enrichment, parsing and sync. A failure in one doesn't stop the others, and the sync now records the vector index's own count instead of trusting its local bookkeeping.
The first run found a deploy gap
The first production run after the merge failed, for a reason the classifier couldn't help with. The change added a new database table and queries, but nothing deployed backend changes before the workflow used them. Enrichment and parsing failed immediately. The isolated sync job still finished.
A second pull request that morning added an automatic production deploy whenever backend files change, serialized so only one deploy runs at a time. The replacement run passed end to end:
- 100 PDFs processed: 87 enriched, 13 deterministic failures quarantined
- 141 parse candidates: 126 parsed, 12 refusals and 3 corrupt OCR documents quarantined
- 227 new observation rows inserted and synced
- zero runtime errors
That run had no outage, so the abort path wasn't exercised in production. The unit tests pin the classification instead: 403, 429 and 503 from FDA, and 400, 401, 404, 429 and 503 from the model, are classed as systemic, which the job turns into an abort, while a context-length error is classed as the document's own problem. The 28 quarantined documents from that run wait for someone to look at them before they're retried.